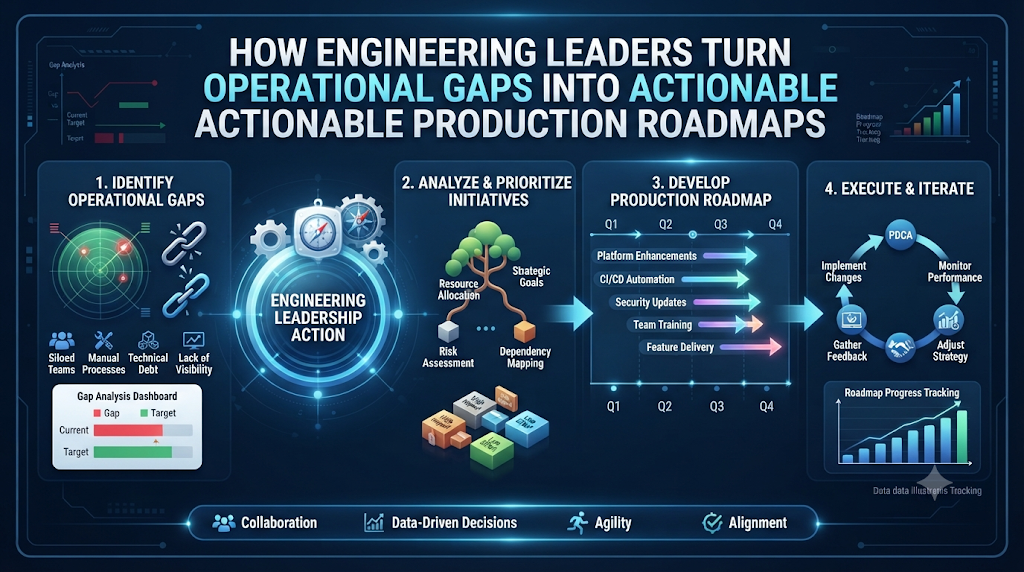
Every growing software team hits a familiar turning point. Early on, shipping features fast feels like the only metric that counts. Then traffic scales, cloud infrastructure multiplies, and small operational blind spots suddenly turn into midnight outages, slow releases, and unpredictable cloud bills.
At that stage, buying another monitoring tool or writing a longer wiki page rarely fixes the root problem. What teams actually need is a clear, honest picture of where their engineering operations stand today—and a step-by-step plan to close the biggest gaps first.
Written from the perspective of an engineering leader and operations architect, this guide shows how to use a production readiness assessment and structured maturity reviews to strengthen live systems. You will learn how to evaluate delivery pipelines, harden Kubernetes workloads, improve incident response, control cloud spend, and build practical roadmaps your engineers will actually follow. To explore structured evaluations, operational checklists, and team roadmaps, visit OpsRoadmaps.
Shifting from Firefighting to Deliberate Operations
Most operational pain comes from invisible assumptions. One squad assumes backups run automatically; another deploys containers without memory limits; a third discovers during an outage that nobody updated the on-call escalation guide.
Deliberate engineering operations replace hope with repeatable habits. Instead of reacting after customers complain, teams evaluate their readiness before major launches and review capability gaps across key disciplines:
- Delivery and Automation: How safely and frequently code moves from commit to live traffic.
- Reliability and Recovery: How well services withstand traffic spikes, node failures, and dependency slowdowns.
- Security and Governance: How consistently vulnerabilities, secrets, and access permissions are controlled.
- Visibility and Cost: How quickly engineers diagnose problems and how clearly spending maps to business value.
Reality Check: An assessment score is a compass, not a trophy. High maturity ratings do not certify regulatory compliance or guarantee zero downtime. Real confidence comes from pairing structured self-reviews with live telemetry, game-day drills, and incident history.
Assessing Current Capabilities Before Building Roadmaps
Before deciding which tools to adopt or which processes to change, establish an honest baseline. Two foundational reviews give engineering organizations immediate clarity.
Running a Production Readiness Assessment
A production readiness assessment examines whether a specific service, platform component, or major release is prepared for live user traffic. Rather than relying on informal sign-offs, the team checks concrete evidence across five areas:
- Ownership and Escalation: Named service owners, active on-call schedules, and reachable escalation contacts exist.
- Failure Handling: Timeouts, retries, circuit breakers, and tested rollback steps are in place.
- Telemetry and Alerting: Actionable alerts tied to user impact exist, backed by clear troubleshooting runbooks.
- Capacity and Resilience: Load expectations are documented, and automated scaling or failover has been verified.
- Security and Data Protection: Secrets are managed outside source code, least-privilege access is enforced, and backups are tested.
Conducting a DevOps Maturity Assessment
While readiness reviews focus on a service or launch, a DevOps maturity assessment looks across the broader engineering organization. It evaluates how smoothly development and operations collaborate across version control, automated testing, Continuous Integration and Continuous Delivery (CI/CD), infrastructure provisioning, and post-incident learning.
Teams at early stages rely heavily on manual approvals and hero engineers. Higher-maturity teams automate routine checks, ship small changes safely, and treat operational reliability as a shared engineering responsibility rather than a separate ticket queue.
Building Domain-Specific Engineering Roadmaps
Once you know where your gaps live, avoid trying to fix everything at once. Break improvements into focused, sequenced tracks tailored to your architecture and team size.
1. Platform Engineering Adoption Roadmap
When product teams spend half their sprint wrestling with Terraform modules, CI YAML files, and cluster permissions, delivery slows down. A platform engineering adoption roadmap solves this friction by treating internal infrastructure as a product for developers.
- Start with Developer Interviews: Identify the top two workflows that cause the most tickets or delays—often environment provisioning or service deployment.
- Build Golden Paths, Not Cages: Offer self-service templates with built-in security, logging, and deployment defaults while allowing advanced teams to customize when needed.
- Measure Adoption Voluntarily: Track how many services choose the paved road and how fast new engineers ship their first change.
2. SRE Adoption Roadmap
Site Reliability Engineering (SRE) brings engineering discipline to uptime and operational toil. A practical SRE adoption roadmap introduces reliability practices gradually:
- Define SLIs and SLOs: Pick meaningful Service Level Indicators (such as request success rate and p95 latency) and agree on realistic Service Level Objectives with product stakeholders.
- Use Error Budgets for Decisions: When reliability stays within budget, teams ship features at full speed; when outages burn the budget, engineering prioritizes stability work.
- Automate Repetitive Toil: Identify manual operational tasks that scale linearly with traffic and replace them with software automation.
3. DevSecOps Implementation Roadmap
Security bottlenecks happen when vulnerability scans and architecture reviews occur days before release. A DevSecOps implementation roadmap shifts checks directly into everyday developer workflows:
- Automate Pipeline Guardrails: Scan source dependencies, container images, and Infrastructure as Code (IaC) templates automatically on every pull request.
- Lock Down Secrets and Identities: Replace long-lived static credentials with short-lived tokens, managed secret stores, and least-privilege Identity and Access Management (IAM) roles.
- Prioritize Fixes by Exposure: Focus remediation first on internet-facing workloads and critical vulnerabilities rather than overwhelming developers with low-risk noise.
4. Cloud Cost Optimization Roadmap
Unchecked cloud growth quietly erodes engineering budgets. A structured cloud cost optimization roadmap brings FinOps habits into daily engineering decisions without sacrificing performance:
- Enforce Cost Allocation Tags: Tag clusters, namespaces, databases, and storage buckets by team, service, and environment so every dollar has an owner.
- Rightsize and Clean Up Waste: Identify idle non-production environments, unattached storage volumes, and over-provisioned compute instances.
- Track Unit Economics: Measure cost per transaction, per active user, or per workload alongside latency and availability so efficiency decisions stay grounded in business value.
Evaluating Observability and Incident Response Maturity
Even the best-designed systems fail in unexpected ways. How quickly your team detects, understands, and recovers from disruption separates resilient organizations from fragile ones.
| Capability Area | Early Stage (Reactive) | Intermediate Stage (Structured) | Advanced Stage (Proactive) |
| Observability Maturity Model | Basic server CPU/memory graphs; engineers SSH into hosts or grep raw logs manually during outages. | Centralized logs and metrics; service dashboards exist, though alerts still fire on noisy infrastructure symptoms. | Standardized telemetry via OpenTelemetry; correlated logs, metrics, and traces with alerts tied directly to SLO burn rates. |
| Incident Management Maturity Model | Ad-hoc chat threads; unclear ownership during outages; fixes rely on senior engineers guessing root causes. | Defined severity tiers, dedicated incident commander roles, status page updates, and basic runbooks. | Automated alert routing, rehearsed game days, blameless postmortems, and tracked preventive action items. |
Using an observability maturity model alongside an incident management maturity model helps leaders spot mismatches—for instance, having expensive dashboards that nobody trusts during a real outage, or running postmortems whose action items never enter sprint planning.
Hardening Kubernetes Workloads for Live Traffic
Container orchestration adds speed and portability, yet misconfigured clusters create subtle failure modes. Before exposing services to customers, run every workload through a Kubernetes production readiness checklist:
- Right-Sized CPU and Memory: Set realistic
requestsso Kubernetes schedules pods accurately, and configure memorylimitscarefully to prevent noisy neighbors from starving critical workloads. - Tuned Health Probes: Separate
startupProbe,readinessProbe, andlivenessProbesettings so slow-starting applications finish initializing before receiving traffic or facing premature restarts. - Disruption and Scaling Controls: Configure multiple replicas,
PodDisruptionBudgets, andHorizontalPodAutoscalersso routine node upgrades do not drop live user sessions. - Pod and Network Hardening: Run containers as non-root users, restrict privilege escalation, and apply
NetworkPoliciesso compromised pods cannot freely reach unrelated databases.
YAML
apiVersion: policy/v1
kind: PodDisruptionBudget
metadata:
  name: order-service-pdb
  namespace: commerce
spec:
  minAvailable: 2
  selector:
    matchLabels:
      app: order-service
Practical Runbook: Kubernetes CrashLoopBackOff Troubleshooting
When an alert fires for a restarting pod, calm, systematic diagnosis saves valuable recovery minutes. Mastering Kubernetes CrashLoopBackOff troubleshooting means understanding that CrashLoopBackOff is Kubernetes waiting progressively longer between restarts because a container keeps exiting shortly after launch.
Step 1: Inspect Pod Events and Exit Codes
Start with read-only commands to see what kubelet observed:
Bash
kubectl get pods -n commerce
kubectl describe pod order-service-6b8d9f4c7-m9x2q -n commerce
Check the Last State and Events output carefully:
- Exit Code 137 (
OOMKilled): The container consumed more memory than its definedlimits.memoryand was terminated by the Linux kernel. - Exit Code 1 or 2: The application exited on its own—typically due to a missing environment variable, invalid config file, or unreachable database.
- Liveness Probe Failures: Kubernetes killed a healthy-but-slow container because
livenessProbetimed out too early.
Step 2: Read Logs from the Crashed Container
Standard kubectl logs may show an empty or freshly starting container. Add --previous to inspect the crash output:
Bash
kubectl logs order-service-6b8d9f4c7-m9x2q -n commerce --previous
Step 3: Apply a Targeted Fix and Confirm Stability
- For configuration or secret errors, update the ConfigMap, Secret, or deployment environment variables.
- For
OOMKilledevents, profile application memory usage and adjustresources.limits.memoryor fix memory leaks. - For premature probe kills, add a
startupProbeor increaseinitialDelaySeconds.
After applying the updated manifest, confirm that new pods stabilize without incrementing restart counters:
Bash
kubectl rollout status deployment/order-service -n commerce
kubectl get pods -n commerce -w
Note: Avoid deleting pods blindly as a fix—a Deployment controller will simply recreate the broken pod with the exact same configuration unless the underlying issue is resolved.
Choosing the Right Metrics Without Distorting Behavior
Metrics work best when they illuminate bottlenecks rather than punish teams. Combine three complementary lenses:
- Delivery Flow and Stability (DORA): Track deployment frequency, lead time for changes, change failure rate, and time to restore service to see whether speed and stability improve together.
- Customer Experience (SLIs and SLOs): Measure availability and latency from the user’s perspective rather than relying solely on server health checks.
- Operational Efficiency: Monitor on-call page volume per engineer, runbook coverage for critical alerts, and cloud cost per unit of business output.
Avoid declaring universal numeric targets across every team. A regulated financial service and an internal analytics pipeline carry very different risk profiles and deserve tailored thresholds.
Common Organizational Pitfalls to Watch For
Even experienced engineering leaders stumble when rolling out operational improvements. Steer clear of these four traps:
- Tool-First Thinking: Purchasing a new observability suite or internal portal does not solve unclear service ownership or missing runbooks. Define the workflow first, then pick the tool.
- All-or-Nothing Rollouts: Mandating a 60-item readiness gate across every legacy service overnight creates resentment and workarounds. Start with tier-one services and expand incrementally.
- Ignoring Cultural Safety: If postmortems turn into blame sessions, engineers hide near-misses and maturity assessments become fiction. Reward honest gap discovery.
- Set-and-Forget Assessments: Architecture, traffic, and team structures shift every quarter. Schedule lightweight reassessments so roadmaps stay aligned with reality.
Connecting Assessments to Roadmaps with OpsRoadmaps
Translating operational observations into a clear quarterly plan takes structure. OpsRoadmaps is built specifically for engineering organizations that want to evaluate their operational capabilities, uncover hidden gaps across disciplines like DevOps, SRE, platform engineering, security, observability, and cloud operations, and organize findings into prioritized improvement roadmaps. By pairing explainable capability evaluations with practical checklists, runbooks, and templates, teams can align engineers and leadership around measurable next steps rather than scattered ad-hoc fixes.
Frequently Asked Questions (FAQs)
1. When should an engineering team run a production readiness assessment?
Run one before launching a new customer-facing service, ahead of major architectural migrations, and periodically for critical existing workloads to catch operational drift.
2. How does a DevOps maturity assessment help engineering managers?
It provides a structured baseline across delivery automation, testing, deployment safety, and cross-team collaboration so leaders can prioritize high-impact improvements backed by evidence.
3. What are the highest-priority items on a Kubernetes production readiness checklist?
Accurate CPU and memory requests and limits, properly tuned readiness and liveness probes, multi-replica availability with PodDisruptionBudgets, least-privilege security controls, and actionable alerts.
4. Why do many platform engineering initiatives stall early?
They often fail when platform teams build complex internal abstractions in isolation instead of solving real developer bottlenecks through simple, well-documented golden paths.
5. What is a realistic first milestone in an SRE adoption roadmap?
Start by defining two or three user-focused SLIs and SLOs for your most critical service, creating runbooks for its top alerts, and running blameless postmortems after incidents.
6. How can teams advance along an incident management maturity model?
Establish clear severity definitions, assign dedicated incident roles, standardize communication templates, and ensure post-incident action items are tracked to completion.
7. Where should teams begin with a DevSecOps implementation roadmap?
Begin by automating dependency and container vulnerability scanning in CI pipelines, removing hardcoded secrets, and enforcing least-privilege access across cloud environments.
8. How does an observability maturity model differ from basic monitoring?
Basic monitoring tells you when a known threshold breaks, whereas higher observability maturity correlates logs, metrics, and traces so engineers can diagnose unknown failure modes quickly.
9. What is the safest way to execute a cloud cost optimization roadmap?
Start with accurate resource tagging and cost visibility, eliminate idle non-production resources, rightsize over-allocated workloads, and monitor latency SLOs during any downsizing.
10. What is the fastest way to isolate Kubernetes CrashLoopBackOff troubleshooting causes?
Inspect pod events and exit codes with kubectl describe pod and read the crashed container’s output using kubectl logs <pod-name> --previous to distinguish memory limits (OOMKilled) from application or probe errors.
Conclusion
Operational excellence rarely comes from a single heroic overhaul. It grows out of clear visibility into your current capabilities, honest prioritization of risk, and steady execution across delivery, reliability, security, and cost.
Pick one high-impact service this week, review its readiness across ownership, alerts, backups, and Kubernetes configuration, and turn the top two gaps into scheduled engineering work. Whenever you want structured capability evaluations, operational checklists, and actionable roadmaps for your organization, explore OpsRoadmaps.
