1. Introduction & Overview
What is a Data Catalog?
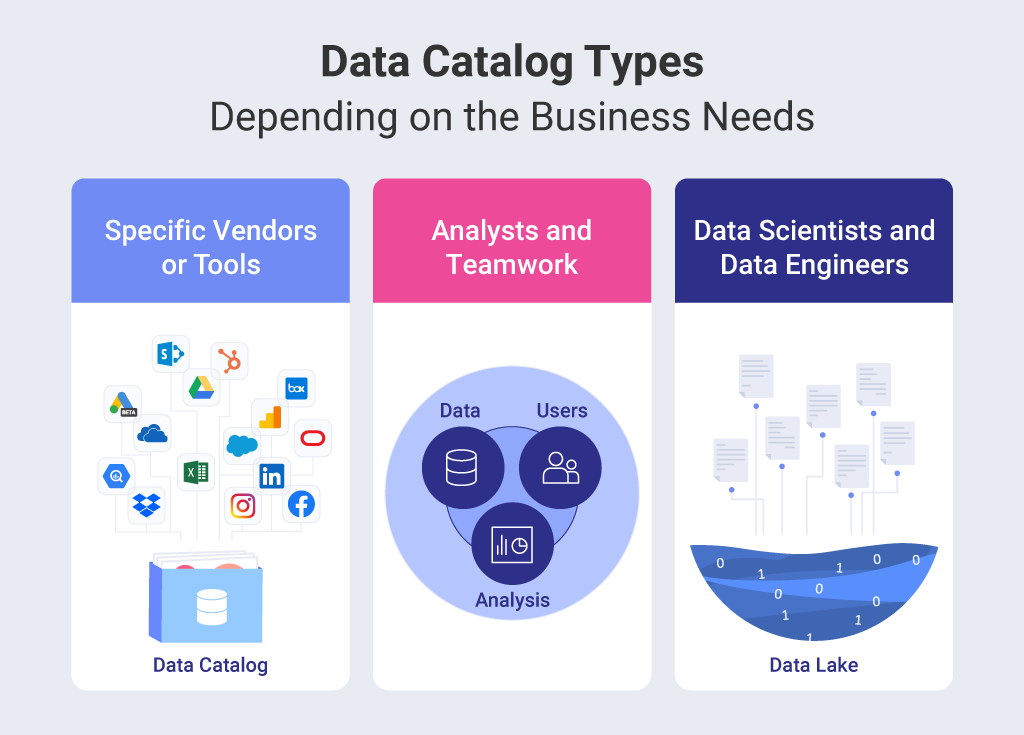
A Data Catalog is a centralized inventory of an organization’s data assets. It enables teams to discover, classify, organize, and govern data across diverse environments (on-prem, cloud, hybrid). A catalog provides metadata, data lineage, and business context, acting as a bridge between raw data and meaningful insights.
In DataOps, a Data Catalog plays the same role as DevOps package repositories (like Maven or npm), ensuring data discoverability, standardization, and trustworthiness.
History or Background
- Early 2000s: Organizations relied on manual data dictionaries and metadata repositories.
- 2010s: Rise of Big Data and Cloud demanded scalable metadata management → tools like Apache Atlas, Alation, and Collibra emerged.
- 2020s: DataOps adopted Data Catalogs as a core automation layer to improve collaboration, compliance, and governance.
- 2025 and beyond: Catalogs are evolving into AI-driven, self-updating knowledge hubs with automatic tagging, lineage, and quality monitoring.
Why is it Relevant in DataOps?
- Data discovery: Analysts/engineers can find datasets quickly.
- Governance & compliance: Helps with GDPR, HIPAA, and other regulations.
- Automation: Integrates with CI/CD pipelines for schema validation and lineage tracking.
- Collaboration: Acts as a “Google for data” across engineering, business, and analytics teams.
2. Core Concepts & Terminology
Key Terms
| Term | Definition |
|---|---|
| Metadata | Data about data (e.g., schema, owner, source, update frequency). |
| Data Lineage | End-to-end visibility of data flow across pipelines. |
| Data Stewardship | Governance process ensuring quality and compliance. |
| Business Glossary | Standard definitions for business terms. |
| Data Profiling | Statistical summaries (e.g., null counts, distributions). |
| Tagging/Classification | Labeling datasets (e.g., PII, financial, sensitive). |
How it Fits into the DataOps Lifecycle
- Plan → Identify available datasets via catalog.
- Develop → Use metadata APIs to validate schema in CI/CD pipelines.
- Test → Automate data quality validation from catalog rules.
- Release → Catalog publishes new data assets for discovery.
- Monitor → Track lineage, ownership, and health.
- Govern → Apply access policies and compliance rules.
3. Architecture & How It Works
Components of a Data Catalog
- Metadata Repository – Stores technical, business, and operational metadata.
- Crawler/Scanner – Discovers new datasets across databases, files, APIs.
- Search & Discovery – UI or API for users to find datasets.
- Lineage Tracker – Visualizes data flow from source to destination.
- Governance Layer – Roles, policies, and access control.
- Integration APIs – Connect with DataOps tools (Airflow, dbt, Jenkins).
Internal Workflow
- Ingestion – Catalog crawlers scan data sources.
- Metadata Extraction – Schema, profiling, and lineage captured.
- Classification – Auto-tagging for PII, domains, or business units.
- Publishing – Assets are searchable by engineers and analysts.
- Integration – CI/CD pipelines consume catalog metadata for validation.
Architecture Diagram (Textual)
 [Data Sources: DBs, APIs, Files]
            │
            ▼
   [Crawler/Scanner] → [Metadata Repository]
            │                  │
            ▼                  ▼
   [Classification]       [Lineage Tracking]
            │                  │
            └──────► [Search & Discovery UI/API]
                           │
                           ▼
            [Integration with DataOps Tools]
Integration Points with CI/CD & Cloud Tools
- CI/CD (Jenkins, GitHub Actions, GitLab CI)
- Validate schema compatibility before deployment.
- Automate catalog updates when pipelines release new datasets.
- Cloud Tools (AWS Glue, GCP Data Catalog, Azure Purview)
- Native connectors for cloud storage & databases.
- Automated PII detection and classification.
- DataOps Tools (Airflow, dbt, Great Expectations)
- Use catalog metadata for data quality testing and lineage tracking.
4. Installation & Getting Started
Basic Setup or Prerequisites
- Python 3.8+
- Docker (for open-source catalogs like Amundsen, DataHub, Atlas).
- Database access credentials.
- Cloud permissions (if integrating with AWS/GCP/Azure).
Hands-On Example: Installing Amundsen (Open-Source Data Catalog)
# Step 1: Clone repo
git clone https://github.com/amundsen-io/amundsen.git
cd amundsen

# Step 2: Start via Docker
docker-compose -f docker-amundsen.yml up

# Step 3: Access UI
http://localhost:5000

# Step 4: Add sample metadata
python examples/sample_loader.py
✔️ You now have a basic Data Catalog running locally.
5. Real-World Use Cases
- Financial Services
- Catalog tracks sensitive PII data lineage for compliance (GDPR, PCI-DSS).
- Automates auditing with lineage reports.
- E-commerce
- Data scientists discover product & user datasets for ML models.
- Catalog helps standardize KPIs like “customer lifetime value”.
- Healthcare
- Catalog enforces HIPAA compliance.
- Provides metadata visibility for patient record systems.
- Media & Entertainment
- Analysts find audience engagement data across platforms.
- Speeds up A/B testing and personalization pipelines.
6. Benefits & Limitations
Key Advantages
- Centralized metadata & discovery.
- Supports compliance and governance.
- Boosts collaboration between technical and business teams.
- Improves trust in data quality.
Common Limitations
- Initial setup and integration effort can be heavy.
- Metadata may become stale without automation.
- User adoption is challenging without strong governance culture.
- Some tools are costly for enterprise scale.
7. Best Practices & Recommendations
- Security Tips
- Use role-based access control (RBAC).
- Encrypt sensitive metadata.
- Enable audit logging for all access.
- Performance & Maintenance
- Schedule automatic crawlers for metadata freshness.
- Integrate with CI/CD for schema drift detection.
- Monitor lineage graphs for broken pipelines.
- Compliance Alignment
- Map catalog tags to compliance categories (GDPR, HIPAA).
- Automate PII detection using ML classifiers.
- Automation Ideas
- Use Airflow operators to auto-update catalog on pipeline runs.
- Trigger alerts when new datasets lack ownership tags.
8. Comparison with Alternatives
| Feature | Data Catalog | Data Dictionary | Data Governance Tool |
|---|---|---|---|
| Metadata Discovery | ✔️ | Limited | Partial |
| Lineage Tracking | ✔️ | ❌ | ✔️ |
| Search & Collaboration | ✔️ | ❌ | ❌ |
| CI/CD Integration | ✔️ | ❌ | Limited |
| Compliance Mapping | ✔️ | ❌ | ✔️ |
👉 Choose a Data Catalog when you need automation, discovery, and integration with DataOps pipelines.
9. Conclusion
Data Catalogs have evolved from static metadata repositories into dynamic, AI-driven hubs powering modern DataOps workflows. They:
- Improve data discovery, trust, and collaboration.
- Ensure governance and compliance at scale.
- Serve as the central nervous system for DataOps pipelines.
Future Trends
- AI-powered auto-tagging and anomaly detection.
- Deep integration with data mesh architectures.
- Cloud-native, serverless catalog services.
Next Steps
- Try open-source tools like Amundsen, DataHub, or Apache Atlas.
- Explore cloud-native catalogs: AWS Glue Data Catalog, GCP Data Catalog, Azure Purview.
- Join communities like:
- Amundsen Community
- DataHub
- Apache Atlas
